médula.tech
How it works

How we build your company's brain.

This is where the technical detail lives: how it's trained, how it connects to your data, how it works with your teams and how it's maintained over time.

The system

A brain doesn't live alone: it needs oxygen.

Owning a model isn't enough. That brain needs to breathe your operational data, feed on your sources and know where it stands. That's the whole system we build.

Your model

trained on what's yours

MÉDULA-CORE
O2Live data
01Your sources
02Country · industry context
03Teams and permissions

MÉDULA/SYSTEM · CONTINUOUS FLOW 24/7

O2

Oxygen: live data

Connected to what your company produces every day. Without constant flow, any model fades out.

01

Food: your sources

Documents, systems, history and your people's judgment. That's what makes it expert in your business and nothing else.

02

Context: country and industry

It starts out knowing how your sector and your country work. It doesn't learn that on the fly.

03

Circulation: it reaches everyone

The brain serves sales, operations and security, with permissions and traceability. If it doesn't circulate, it's useless.

We don't hand over a brain in a box. We hand over the body that keeps it alive and growing.

How it works

First the center. Then everything else.

Three layers, always in this order: the engine we train, the governance that controls it, and the application your teams use.

01capa

The engine (CLM)

A 1B–14B model built on open bases, calibrated with your country and industry context, then trained on your company's real data and sources. Every client gets a different engine.

02capa

Governance

Security, audit, and RAG over your live data: what goes in, what comes out, and who sees what. Connected to the continuous generation of data from your operation.

03capa

The application

A tailored front-end — chat, copilot, or agents — so the business can use it. The interface changes; the brain stays the same and improves over time.

Fine-tuned 7B–14B models outperform +100B models on domain-specific tasks.
Generic LLM via API
Own Medula CLM
Data
goes to a third-party cloud
never leave your infrastructure
Model
not yours, rented by token
yours, trained once and evolves
Cost
variable, rises with every query
fixed and predictable
Accumulated knowledge
stays with the vendor
stays inside the company
Featured case · Ser Humani

The same engine can also orchestrate an entire business.

The same architecture can be the central infrastructure of a business born autonomous. That is Ser Humani: agents completing coordinated objectives among themselves, without point-to-point supervision.

01

The core reads your real sources — ERP, CRM, documents, sensors — and distributes the objective among specialized agents working in parallel.

02

Each team consumes what it needs: sales, operations, and security see different results from the same engine.

03

IT keeps the control plane: permissions, traces, consumption, and a button to stop everything.

Industries

One model per industry. One engine per company.

Every model is born with country and industry context. Then we configure it for your company: sales, customer acquisition, risk, or operations.

How it's configured
01

Country context

local regulation, language, and market

02

Industry context

sector jargon, processes, and compliance

03

Your company

focus on sales, risk, or operations

The architecture is custom-designed so the brain is well oxygenated and the competitive advantage accumulates inside your company.

01

Health

built case: Vitalentic

Receives, prioritizes, and routes patients 24/7 with the judgment of the hospital's best triage.

How is it built?

  • Base fine-tuned with GES Clinical Guidelines, validated against EUNACOM.
  • Anamnesis → C1–C5 classification → routing, 24/7.

A configuration example — the final design is defined with your company, case by case.

01Empathiainterview02Triagenclassification03NexusroutingC4 · triage

scheduled consultation · latency 0.4 s · on-premise

92%

EUNACOM accuracy

02

Aquaculture

built case: Vigil AI

Detects outbreaks in farming centers days before they become visible.

How is it built?

  • Per-cage forecasting: feed, mortality, and climate.
  • Real-time risk score 0-100 with configurable threshold.

A configuration example — the final design is defined with your company, case by case.

risk score · 24h

▲ +56 pts

threshold 6500h06h12h18h24h

alert issued 6 h before event · current 78

feed vs. plan

7 days · −39% loss

03

Social

content moderation

It doesn't just say “toxic”: it explains why, who it attacks, and leaves the criterion auditable.

How is it built?

  • Classifier + judge agent that explains the verdict.
  • High volume with regulatory traceability.

A configuration example — the final design is defined with your company, case by case.

input

“…those people shouldn't have a voice in this country…”

those peopleshouldn'tvoicethis country

1 · intent classifier

animosity
0
derogation
0
dehumanization
0
threat
0
exaltation
0

2 · reasoning judge

›target group identified

›intent to exclude: yes

›ironic context: no

0%

confidence

verdict

derogation

target group: nationality

04

Finance

banking, insurance, factoring & capital markets

Evaluates risk and answers regulation without any sensitive data leaving your institution.

How is it built?

  • RAG over RAN and CMF circulars, citing the real source.
  • Deterministic risk; the model orchestrates and explains.

A configuration example — the final design is defined with your company, case by case.

score decomposition · deterministic

+42income+26history-18exposure+14collateralscore

output

64

/ 100 · traceable

every point is explained by an auditable factor

05

Agriculture

precision agriculture

Turns satellite and drone images into decisions per block, weeks in advance.

How is it built?

  • Drone vision: pests and water stress per block.
  • NDVI + climate to project yield weeks ahead.

A configuration example — the final design is defined with your company, case by case.

NDVI · 30 blocks

5 in stress

0.20.95

block 13

0.30

Irrigate within the next 48 hours.

Upcoming industriesIf yours isn't here, it's because we haven't built it with you yet.

Let's talk about your industry
Infrastructure

The engine is trained inside, on reference hardware.

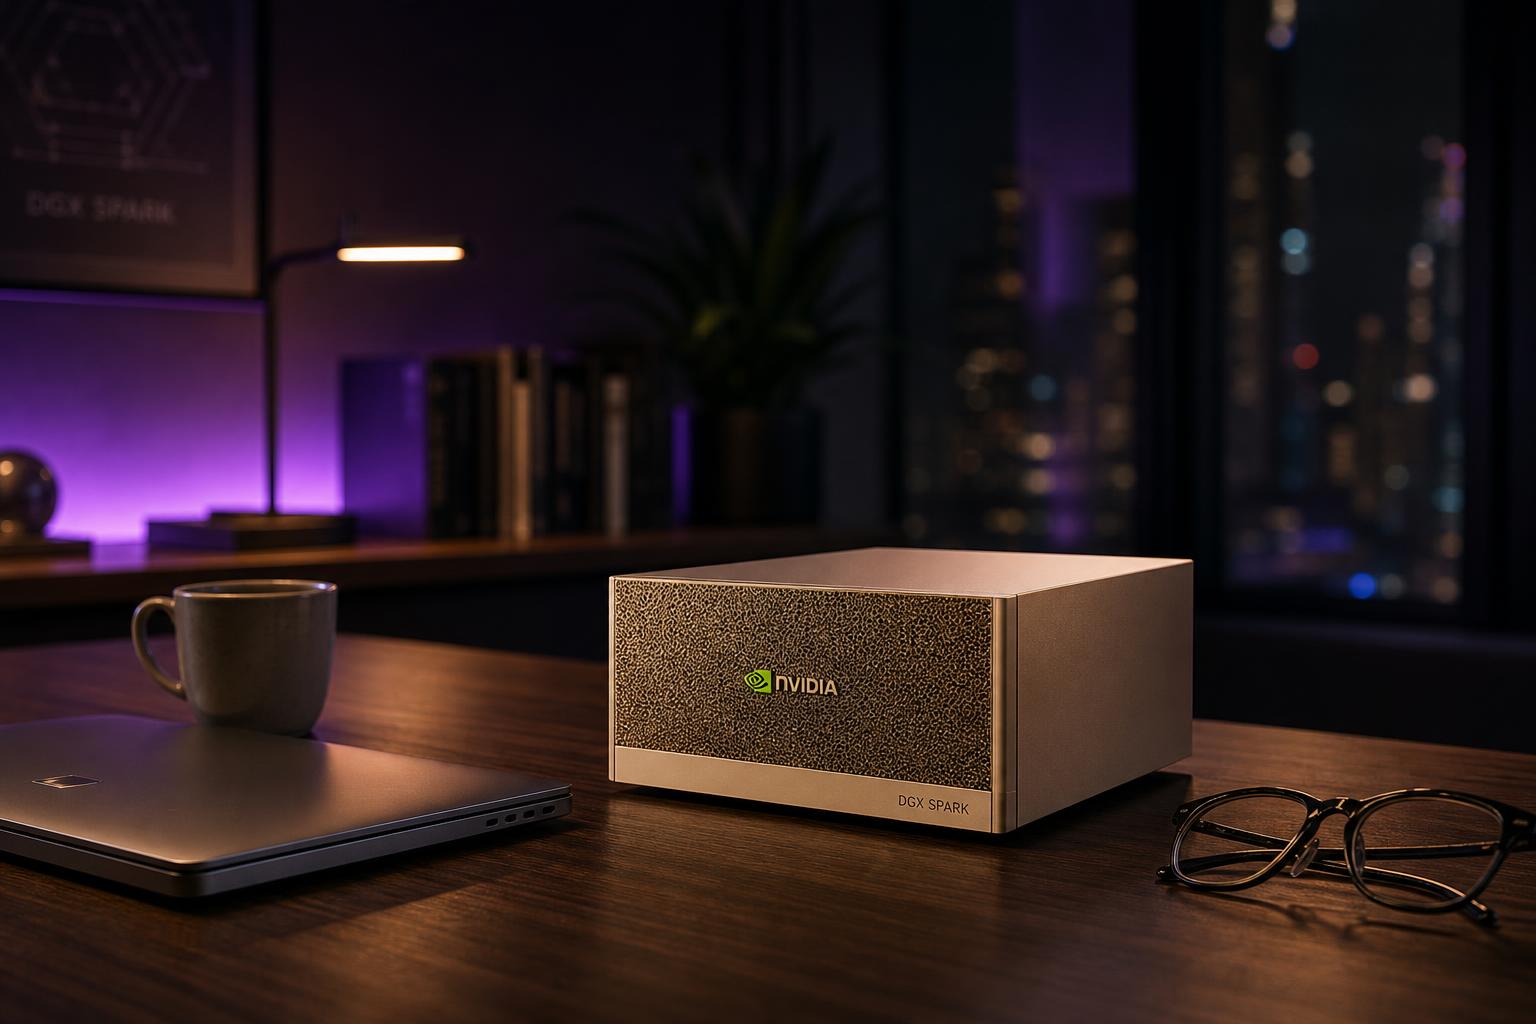
We calibrate and validate your Corporate Language Model on stations like NVIDIA DGX Spark, then transfer it to your own infrastructure.

NVIDIA DGX Spark AI Server Enterprise GPU Computing Platform 4TB 128GB, desktop station on an office desk
NVIDIA DGX SparkEnterprise GPU Computing Platform128 gb · 4 tb

DGX Spark Enterprise reference station.

We calibrate your CLM on the NVIDIA DGX Spark AI Server platform: 128 GB of GPU memory and 4 TB of storage for high-performance local training.

Training inside your perimeter.

The model is trained and operated on your infrastructure. Your data and know-how never leave your network.

Validated handoff to production.

We don't deliver a notebook: we deliver a tested, documented engine ready to be governed by the IT team.

NVIDIANVIDIA technology partner for AI infrastructure.
Who builds the engine?

We don't integrate a model. We train it.

The difference between a demo and something that runs in production, inside a regulated industry, lies in who trains and evaluates the model — not who writes the prompt.

01

PhDs in Mathematics and Data Science.

A team with doctorates in AI, mathematics, and data science. They guarantee precise training, validated with hypotheses, benchmarks, and iteration — better than any generic LLM on the market.

02

Direct relationship with the labs behind the base models.

Technical access to the teams behind the open bases we use, with the latest calibration techniques.

03

Training inside your infrastructure.

The brain is trained inside with your data and your sources. Every company gets a customized model, not a copy of the same engine.

04

Validation against the real sector exam.

Not academic benchmarks: the certification a human professional in that industry would have to pass.

Maintenance

A perfect brain doesn't survive without blood and oxygen.

The model doesn't grow from just any information — it grows from the right information. If your own team feeds it irrelevant, contradictory, or poorly built context, it learns the wrong things, the same way a person would. That's why we don't disappear after installing it: we curate what feeds it, so it grows on what actually matters to your business.

We don't sell a brain and walk away. We keep it alive.

Don't rent your company's brain.

Book 30 minutes and we'll show you what information is leaking out today, unnoticed.